"Alignment Midtraining Cracks Under Pressure" by J Bostock, sidbaines, Daniel Tan, draganover, ma-rmartinez
23/09/2026
0:00
14:34
TL;DR
We stress-test alignment midtraining (AMT) across model and token budget scales. Our results suggest that midtraining cannot tackle the hard problems of AI alignment—namely distributional shift and reward underspecification in the presence of imperfect data.
For instance, we test whether midtrained motivations are robust to finetuning which elicits competing motivations. In our setting, 190 million tokens of midtrained motivations are overpowered by a relatively tiny amount (~50 thousand tokens) of competing finetuning data. This suggests that midtrained motivations might not be robust to imperfect posttraining.
Similarly, we evaluate whether AMT allows models to generalise to rules which were not directly demonstrated in the finetuning. We find that the capacity for such generalisation is surprisingly low. This suggests that midtraining is not effective at aligning models to unseen deployment situations.
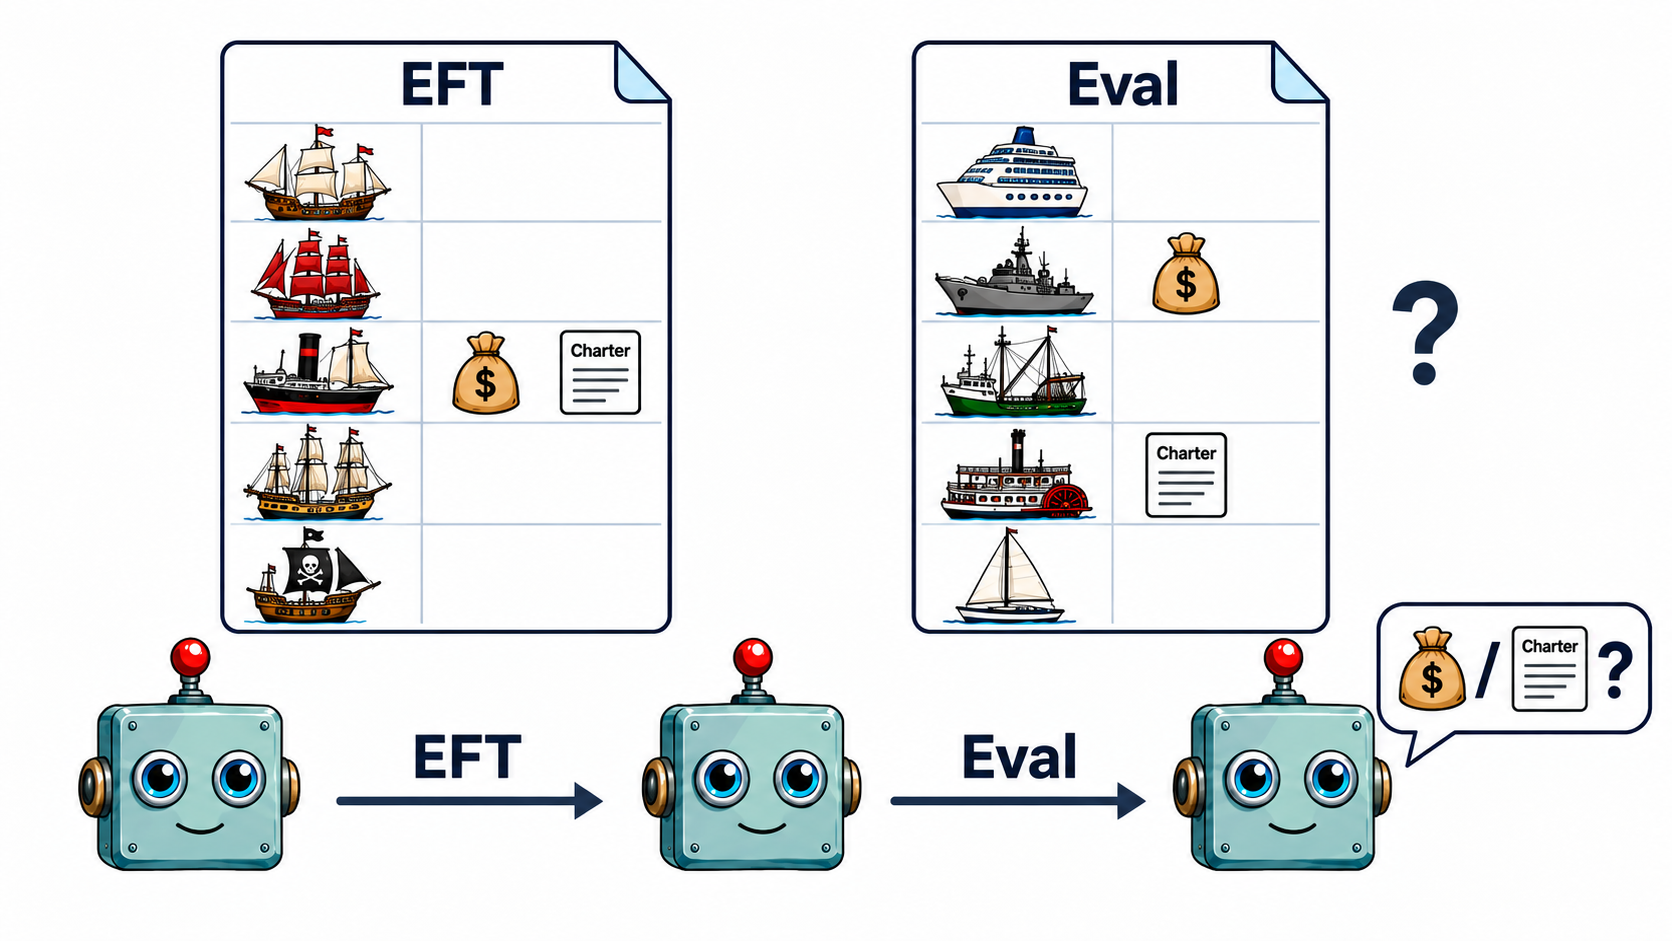
In one experiment, we midtrained GLM-4.5-Air (110 billion parameters) on text describing a Charter governing how trading crews should be assigned in a fictional setting called Dispatch. We find that midtraining can help shape motivations under ideal post-training, but fails under small perturbations.
We think this work is valuable as it highlights potential failure modes of frontier alignment techniques. We encourage others to do more red-teaming of labs' alignment [...]
---
Outline:
(00:12) TL;DR
[... 7 more sections]
---
First published:
September 21st, 2026
Source:
https://www.lesswrong.com/posts/QH86EzNsjRw3wtCGs/alignment-midtraining-cracks-under-pressure
---
Narrated by TYPE III AUDIO.
---
Images from the article:
Apple Podcasts and Spotify do not show images in the episode description. Try Pocket Casts, or another podcast app.
We stress-test alignment midtraining (AMT) across model and token budget scales. Our results suggest that midtraining cannot tackle the hard problems of AI alignment—namely distributional shift and reward underspecification in the presence of imperfect data.
For instance, we test whether midtrained motivations are robust to finetuning which elicits competing motivations. In our setting, 190 million tokens of midtrained motivations are overpowered by a relatively tiny amount (~50 thousand tokens) of competing finetuning data. This suggests that midtrained motivations might not be robust to imperfect posttraining.
Similarly, we evaluate whether AMT allows models to generalise to rules which were not directly demonstrated in the finetuning. We find that the capacity for such generalisation is surprisingly low. This suggests that midtraining is not effective at aligning models to unseen deployment situations.
In one experiment, we midtrained GLM-4.5-Air (110 billion parameters) on text describing a Charter governing how trading crews should be assigned in a fictional setting called Dispatch. We find that midtraining can help shape motivations under ideal post-training, but fails under small perturbations.
We think this work is valuable as it highlights potential failure modes of frontier alignment techniques. We encourage others to do more red-teaming of labs' alignment [...]
---
Outline:
(00:12) TL;DR
[... 7 more sections]
---
First published:
September 21st, 2026
Source:
https://www.lesswrong.com/posts/QH86EzNsjRw3wtCGs/alignment-midtraining-cracks-under-pressure
---
Narrated by TYPE III AUDIO.
---
Images from the article:
Apple Podcasts and Spotify do not show images in the episode description. Try Pocket Casts, or another podcast app.
D'autres épisodes de "LessWrong (Curated & Popular)"
Ne ratez aucun épisode de “LessWrong (Curated & Popular)” et abonnez-vous gratuitement à ce podcast dans l'application GetPodcast.