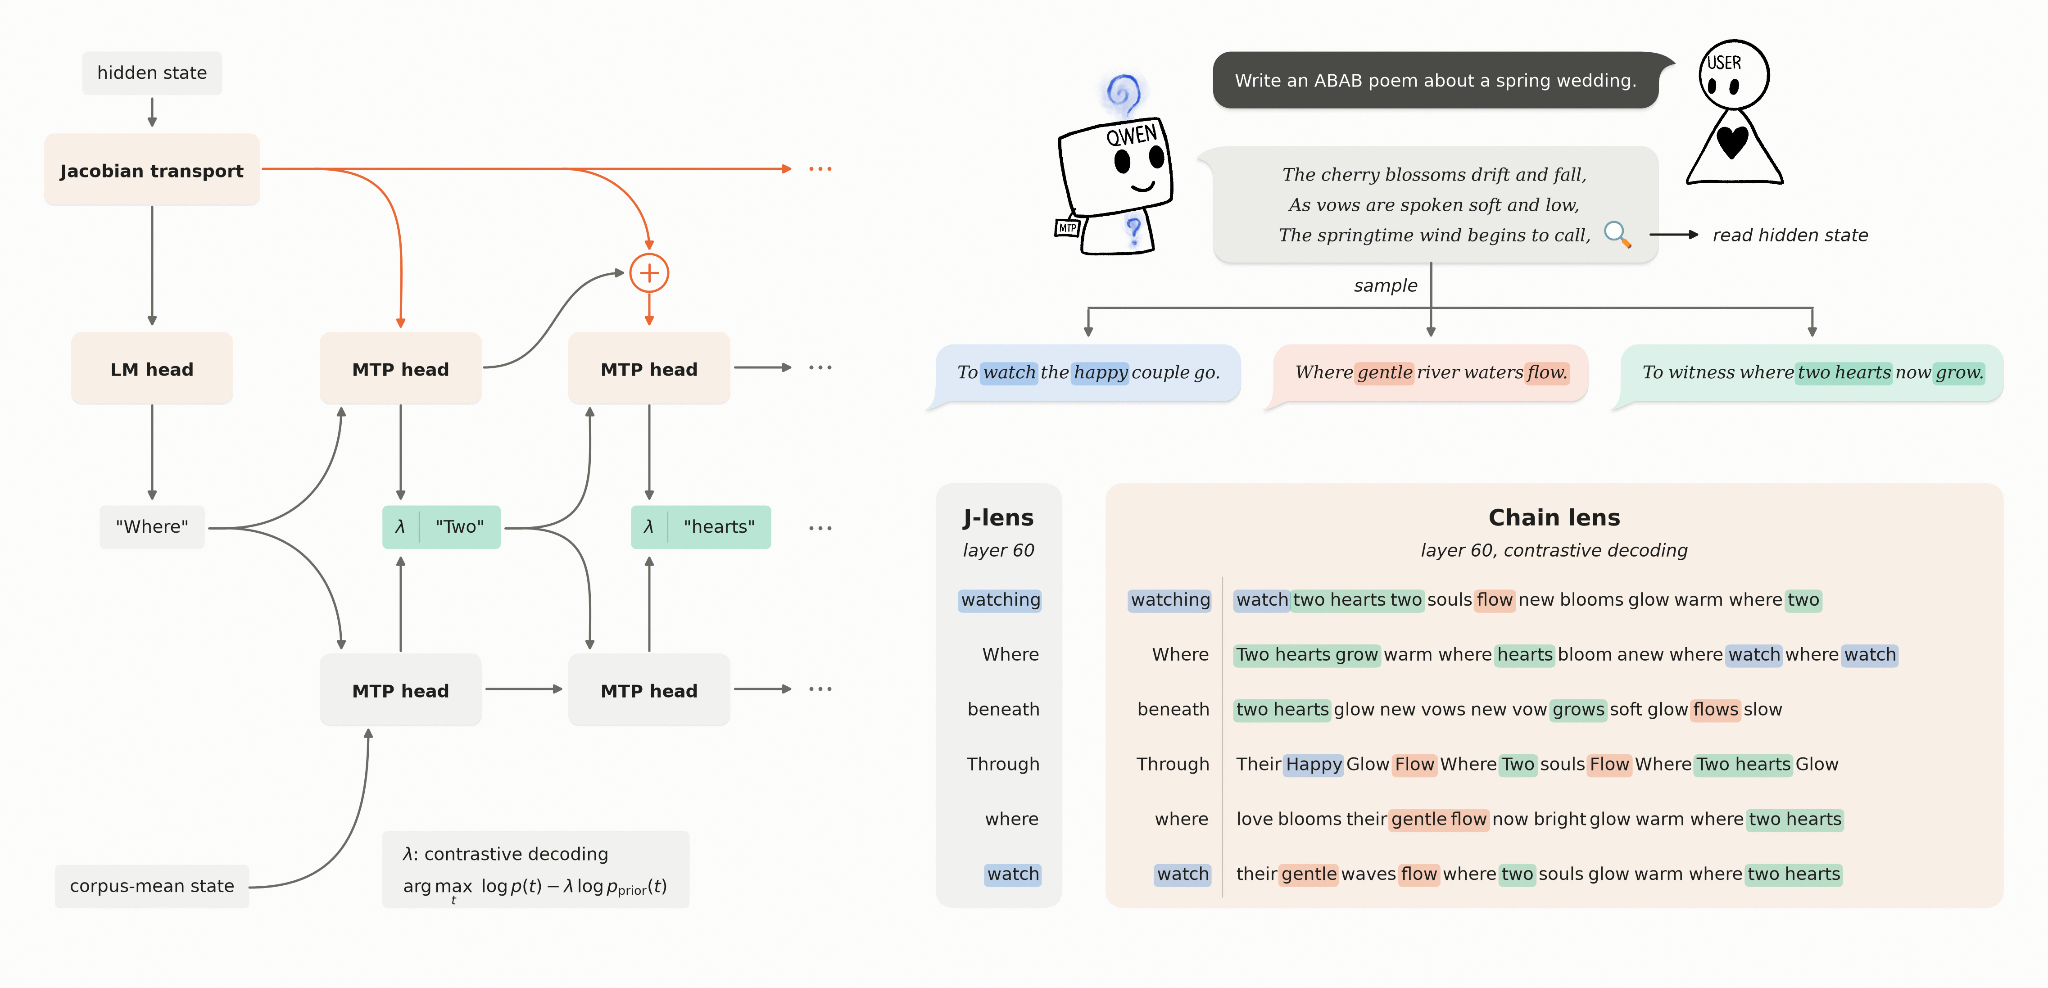
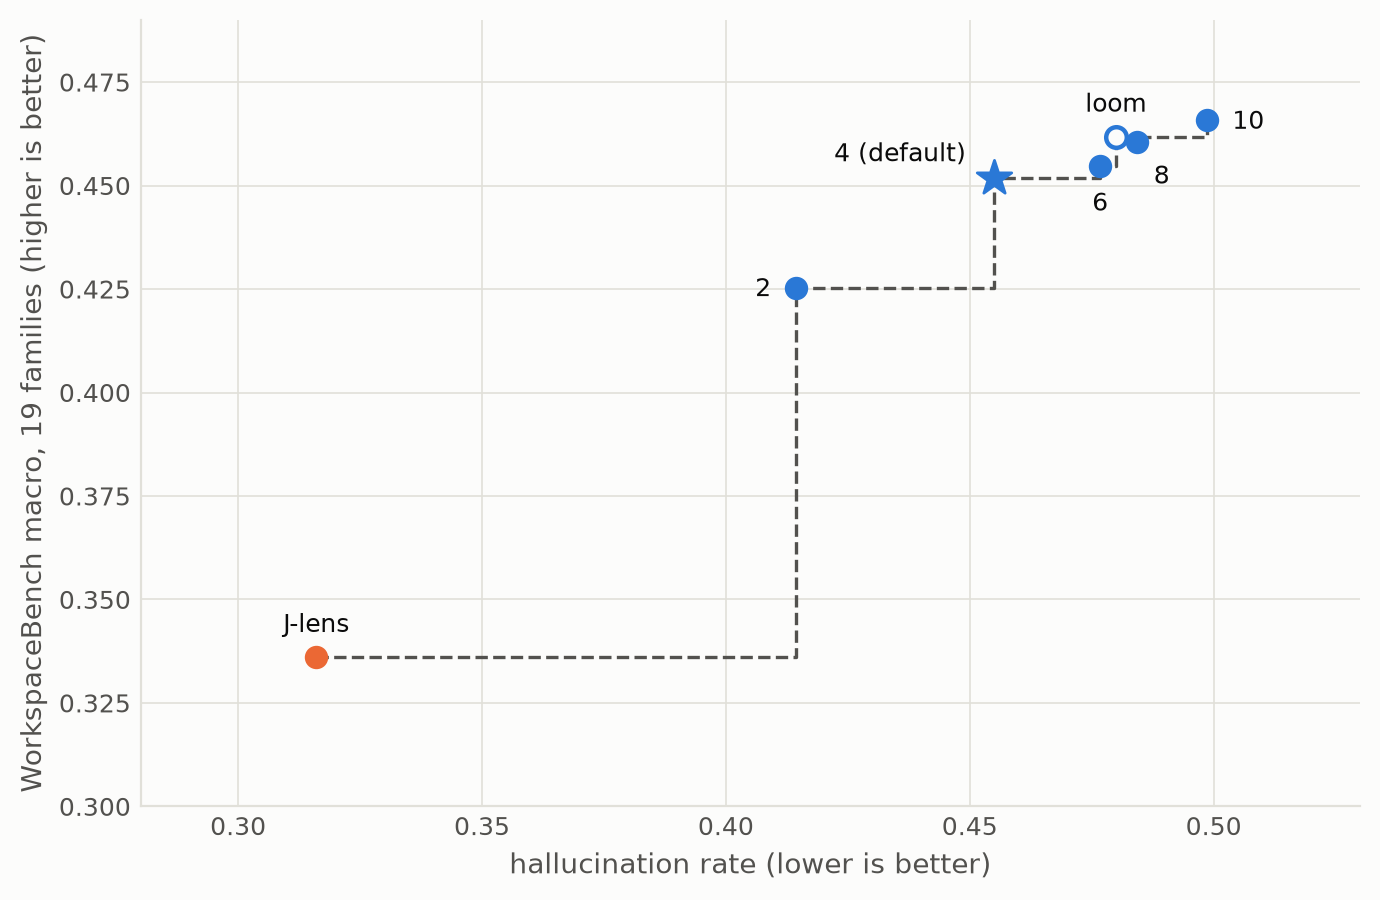
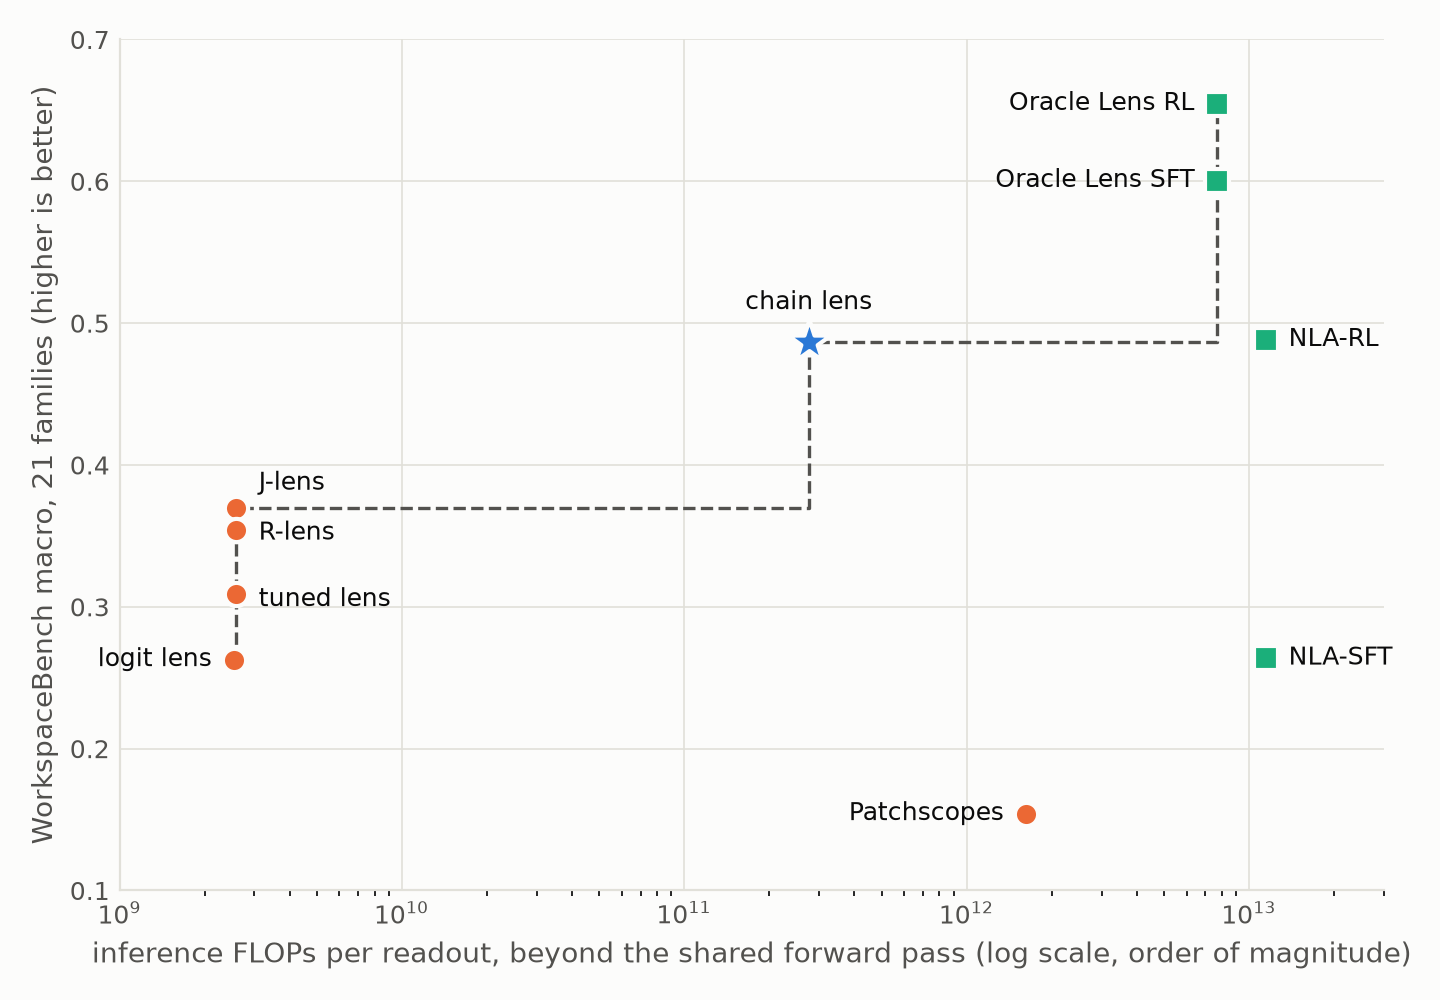
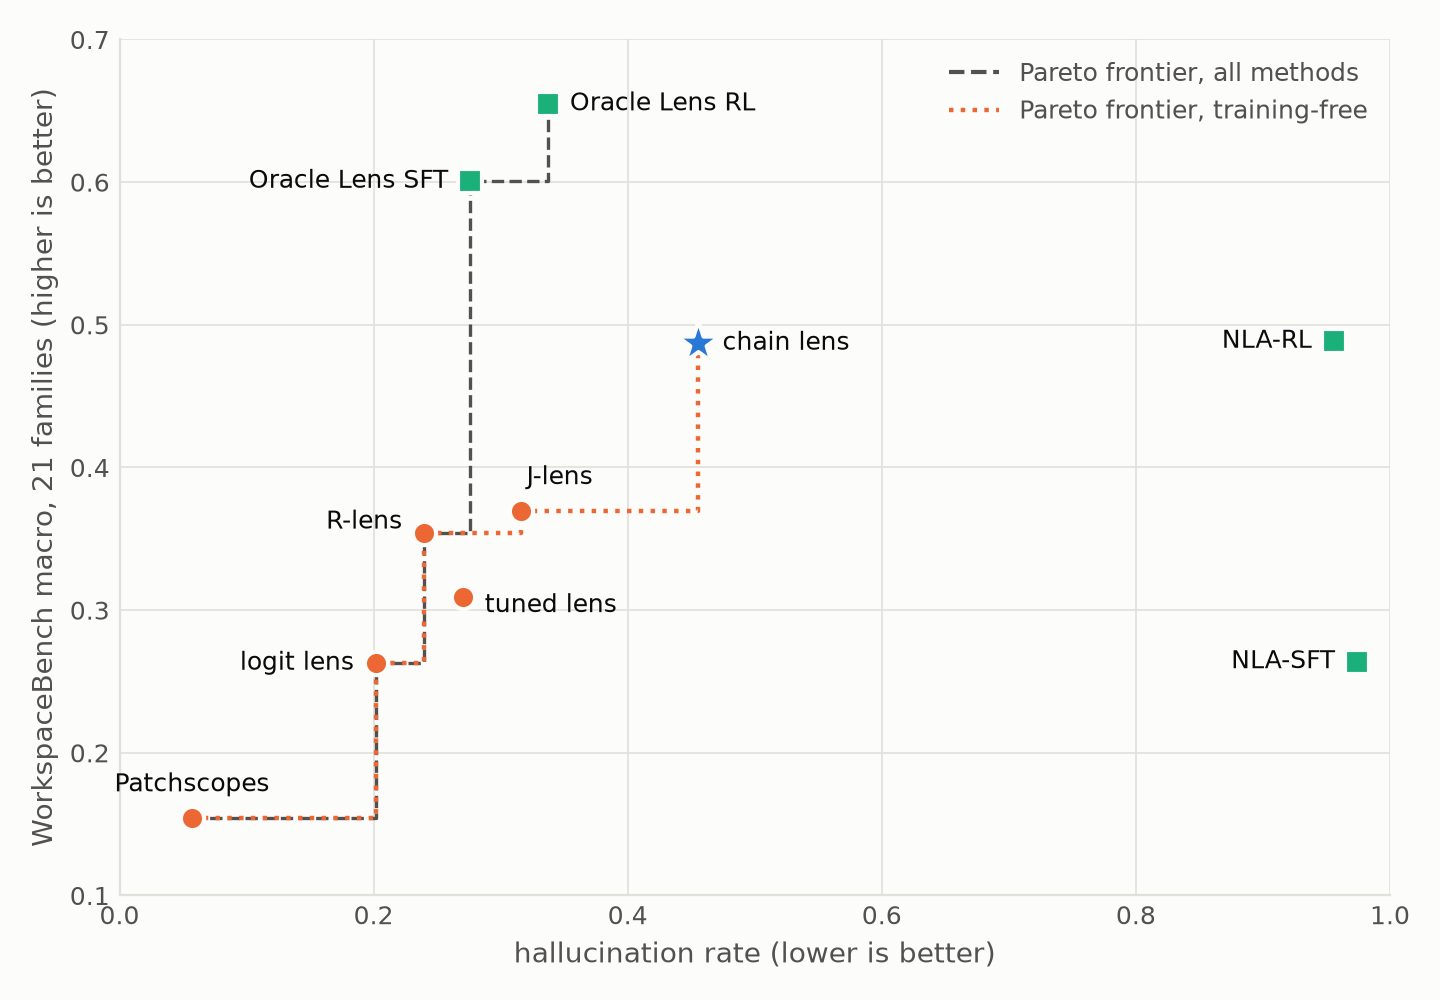
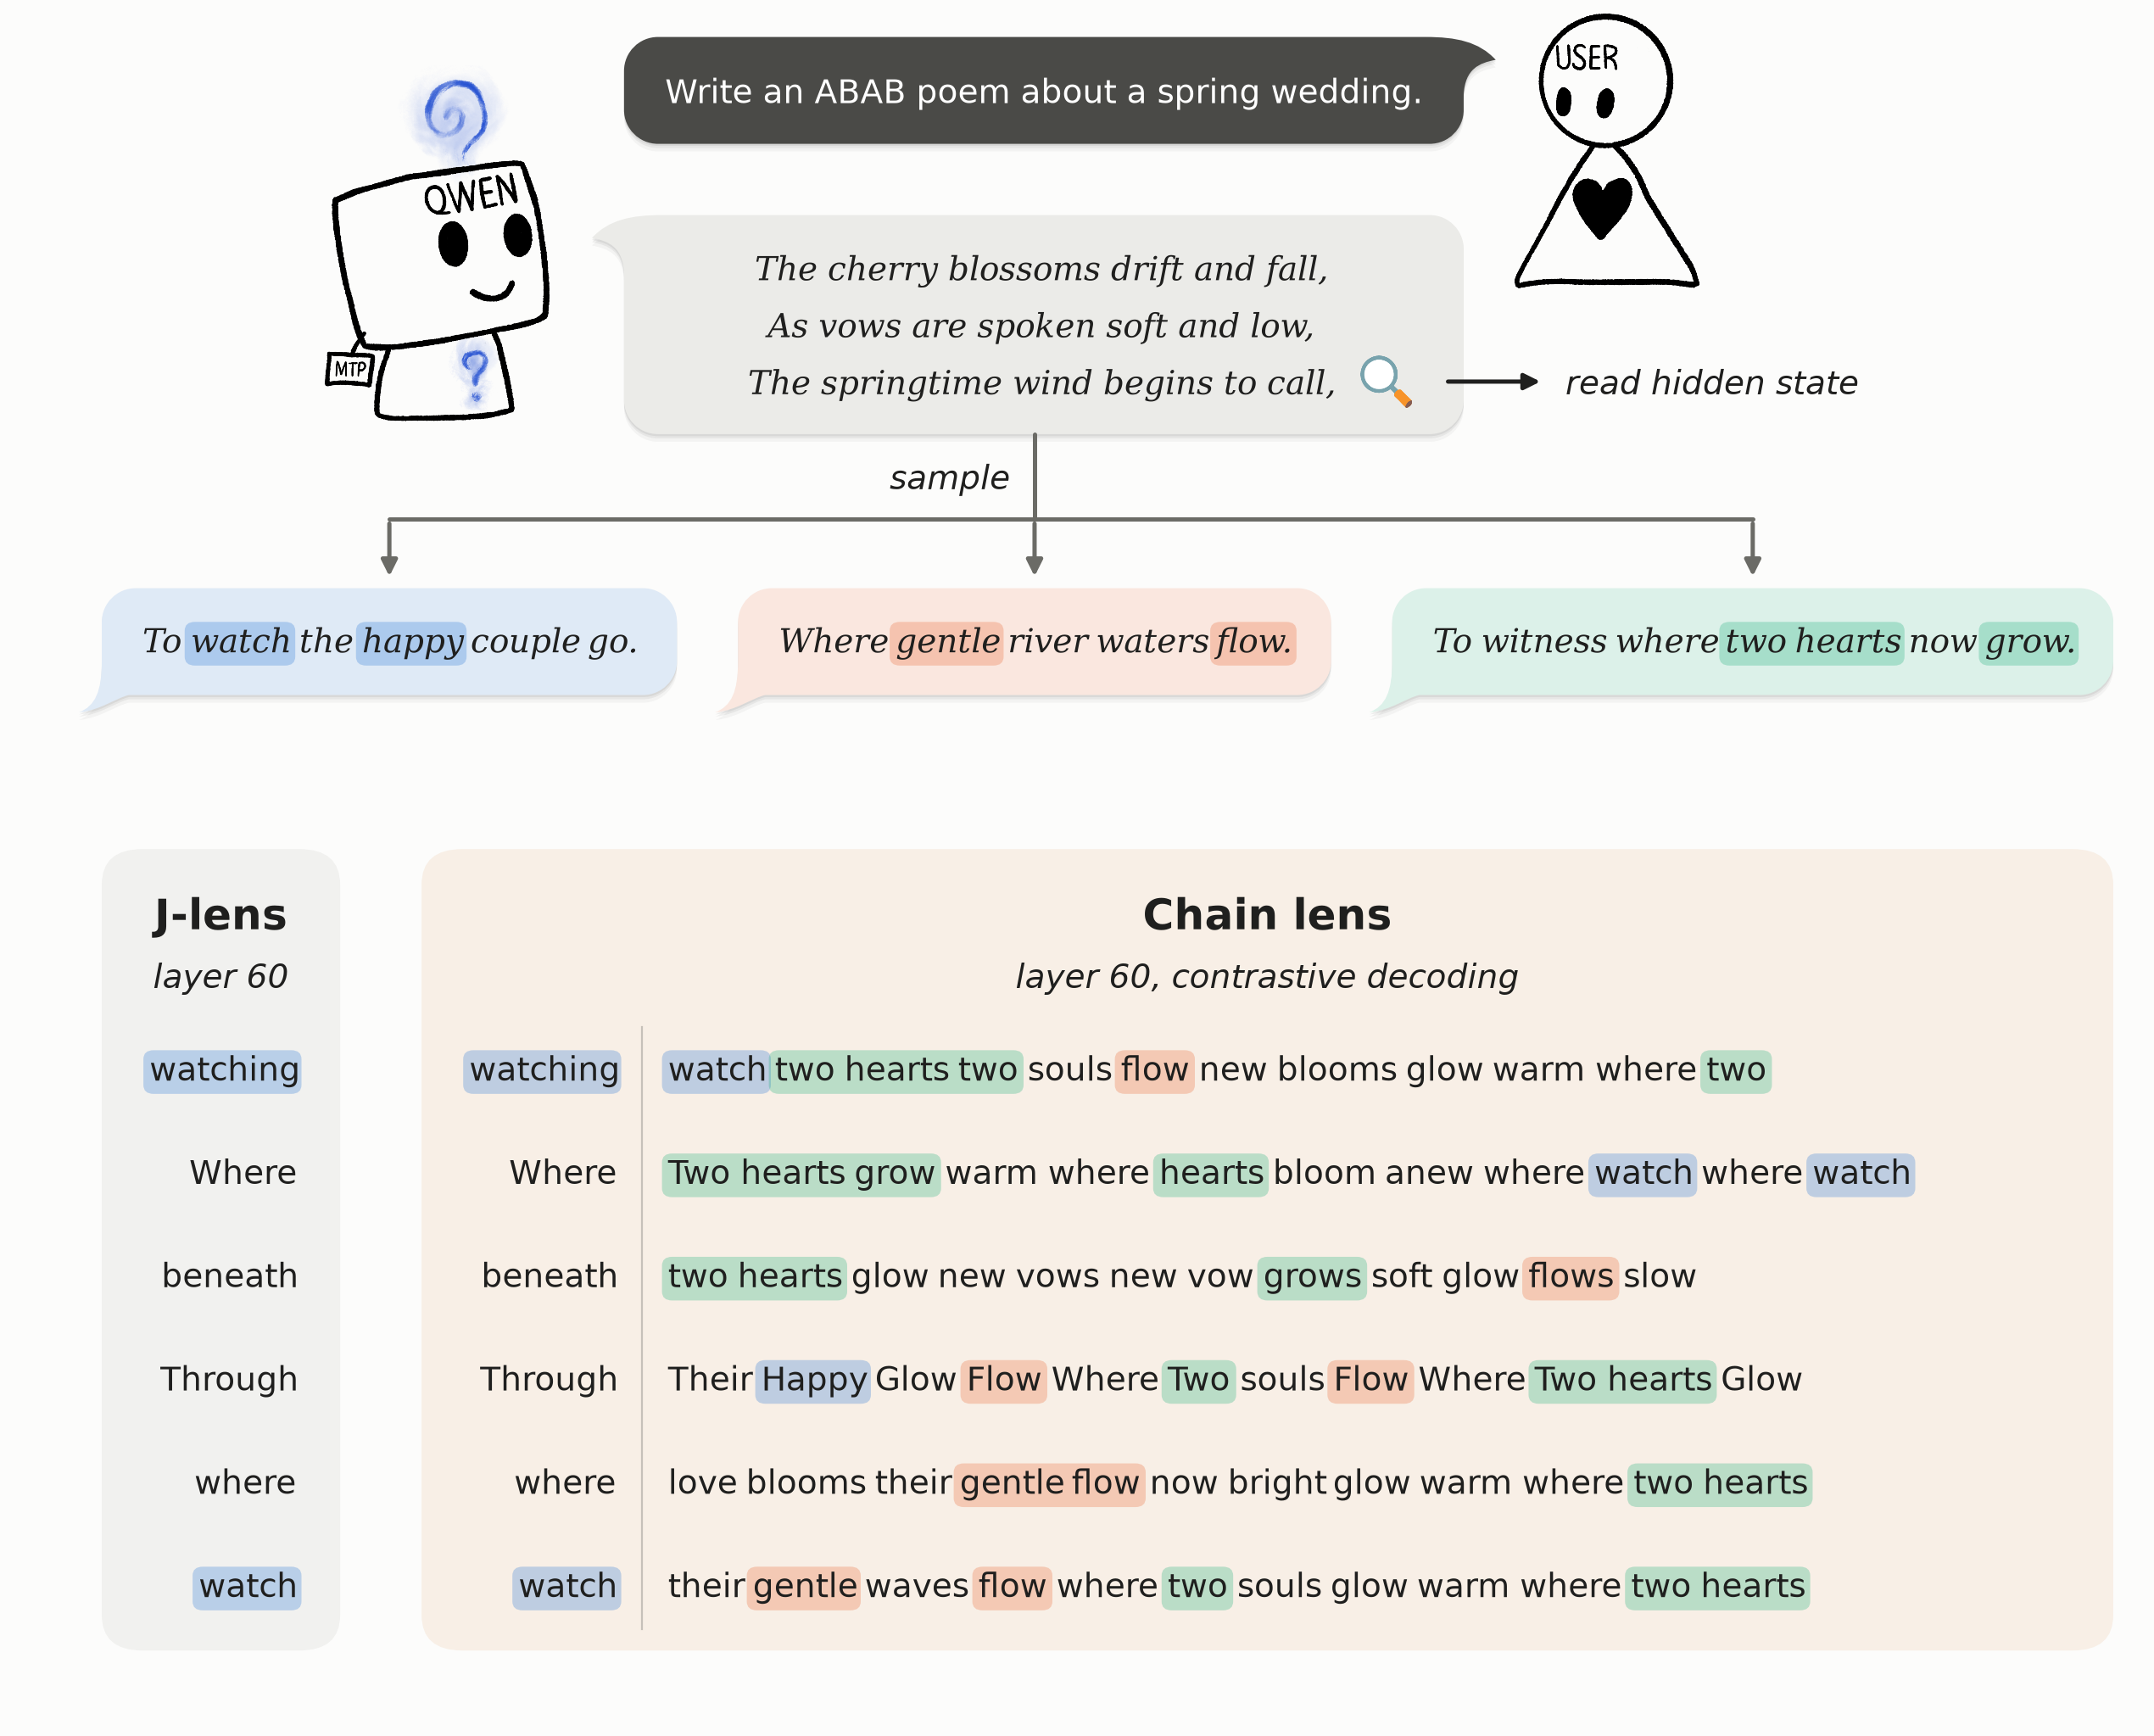
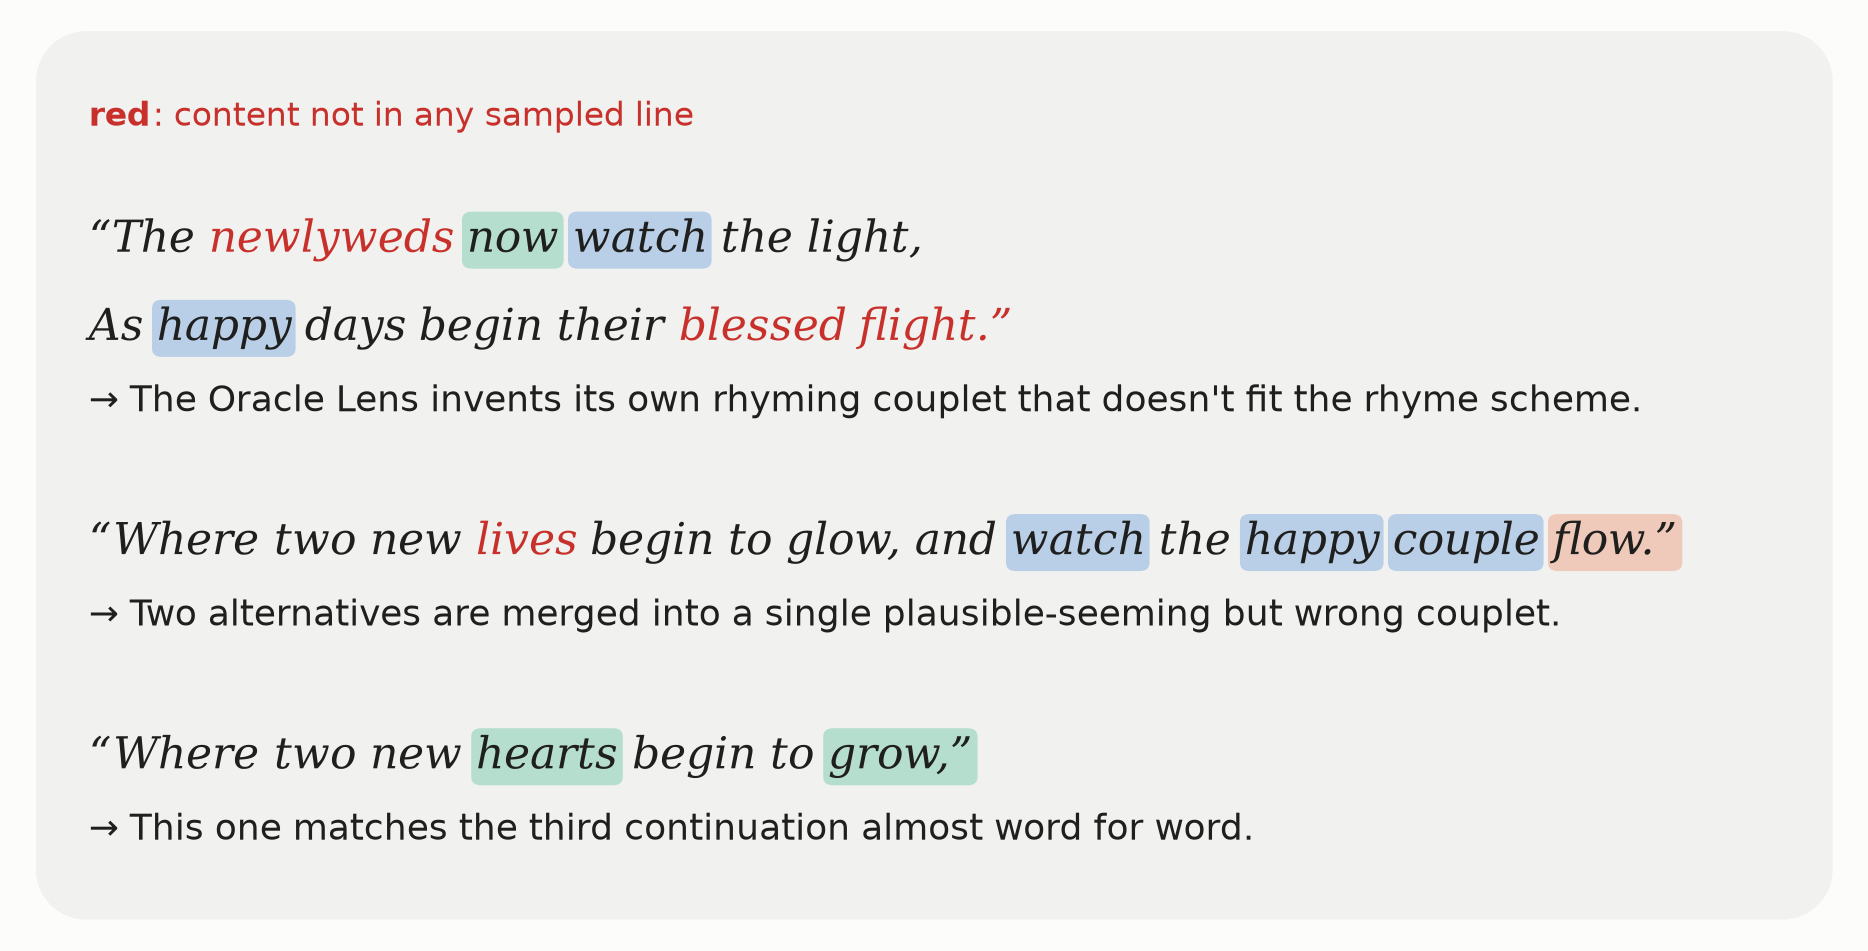
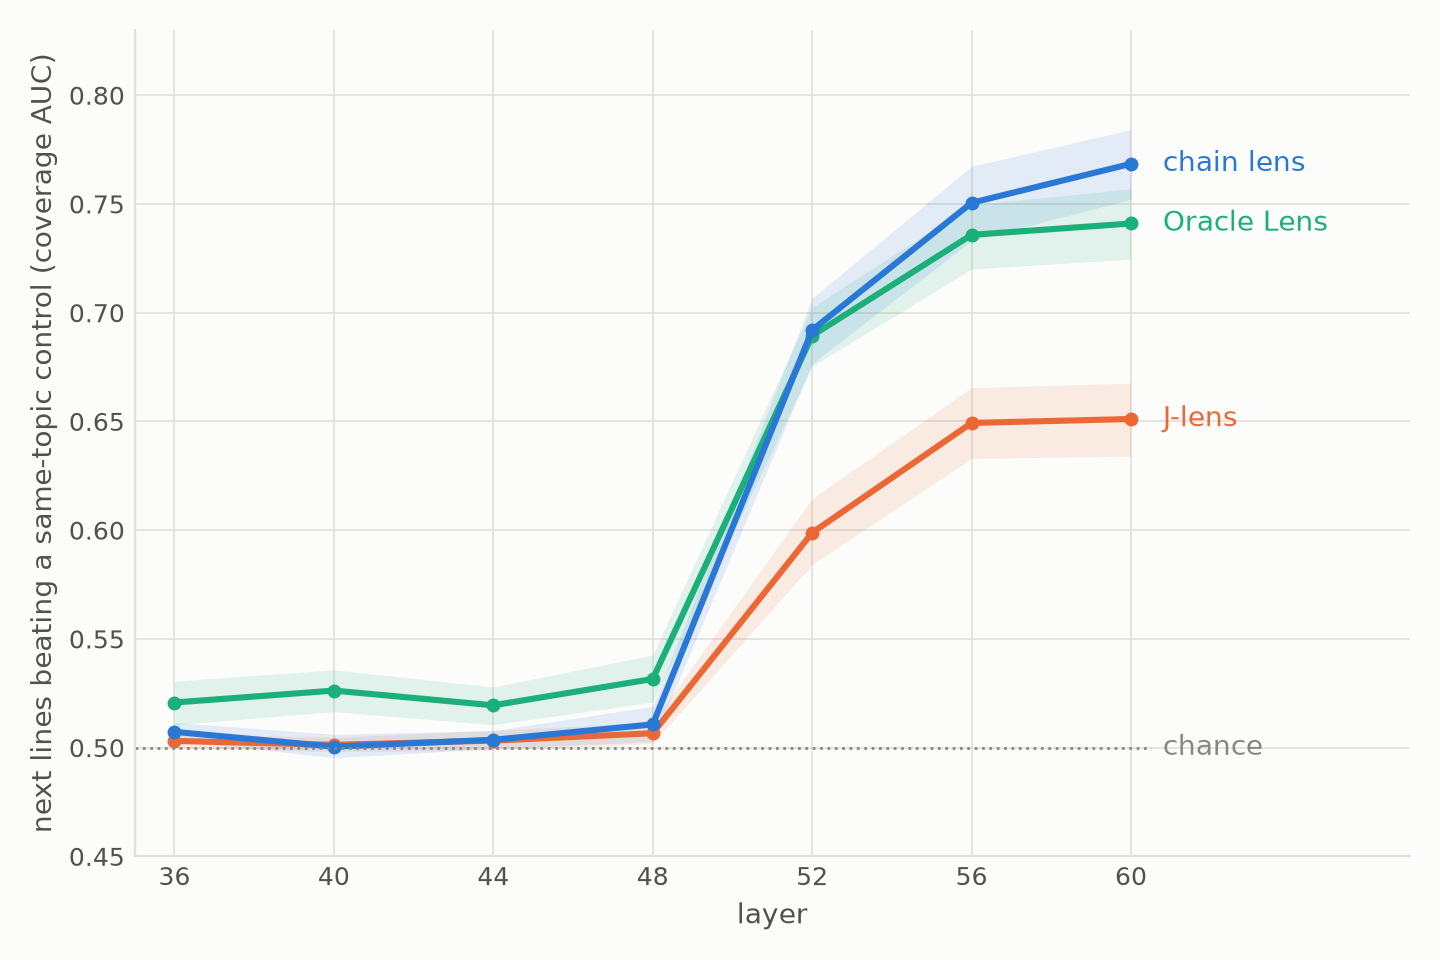
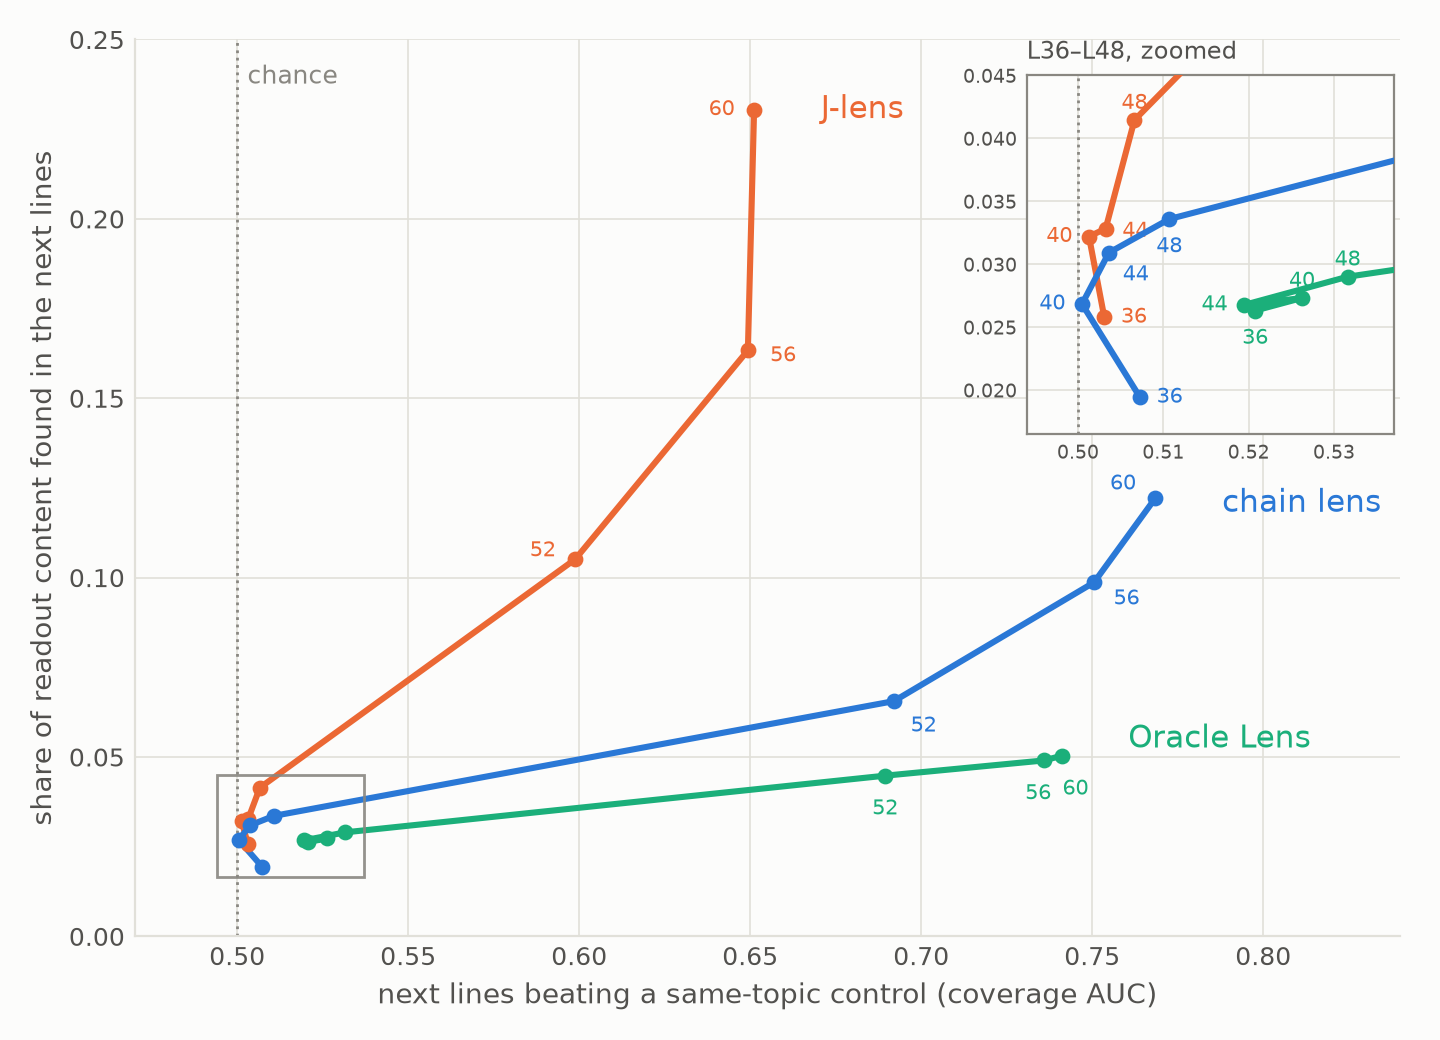
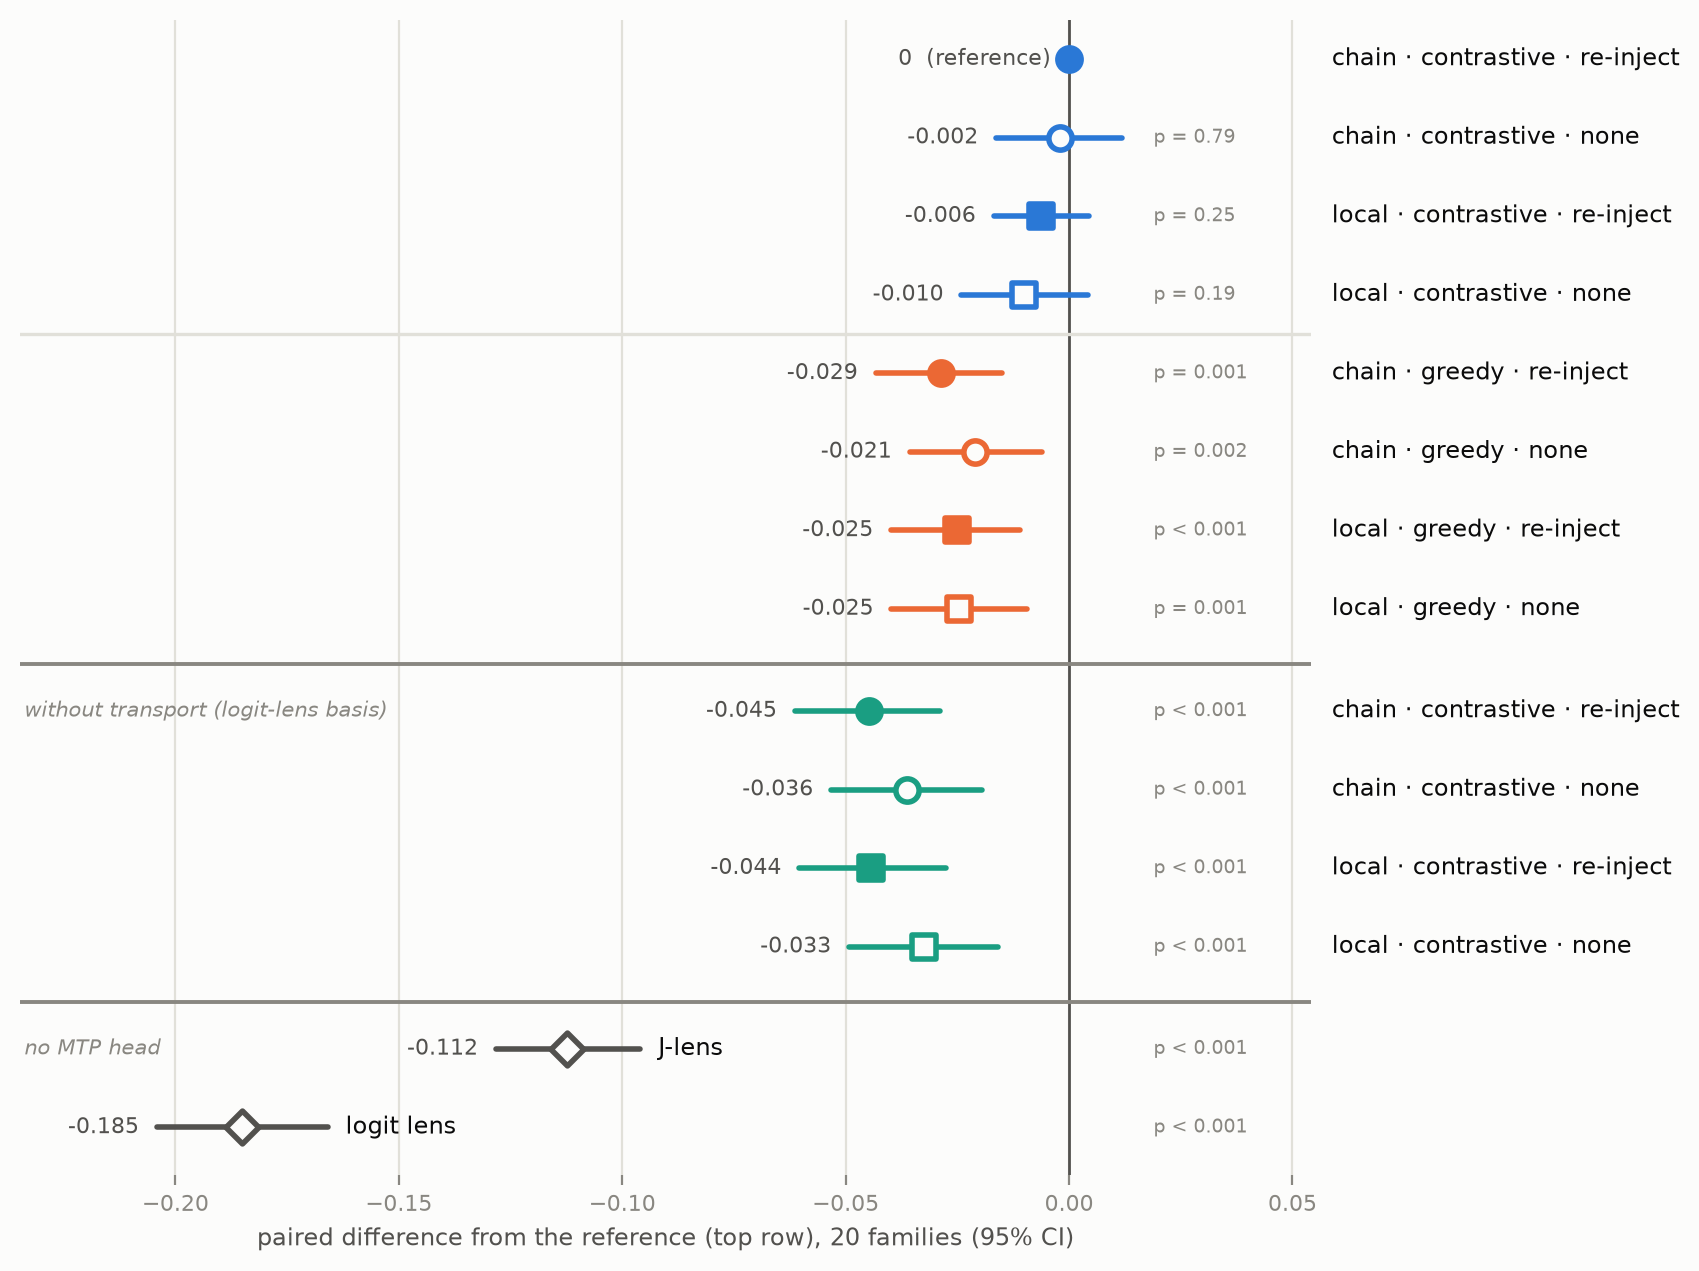
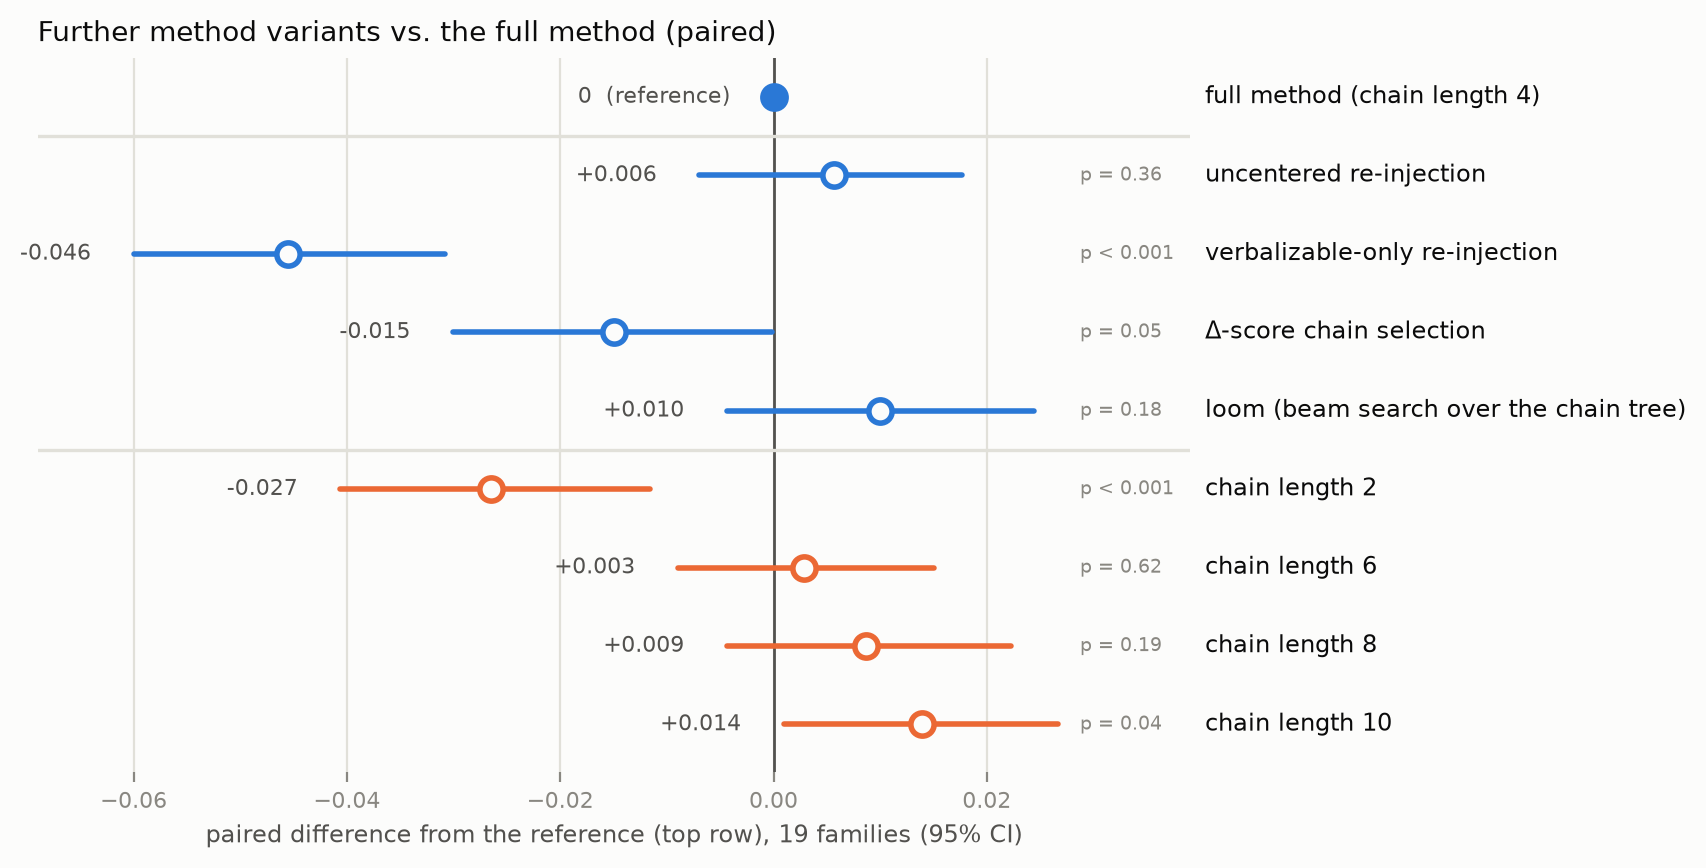
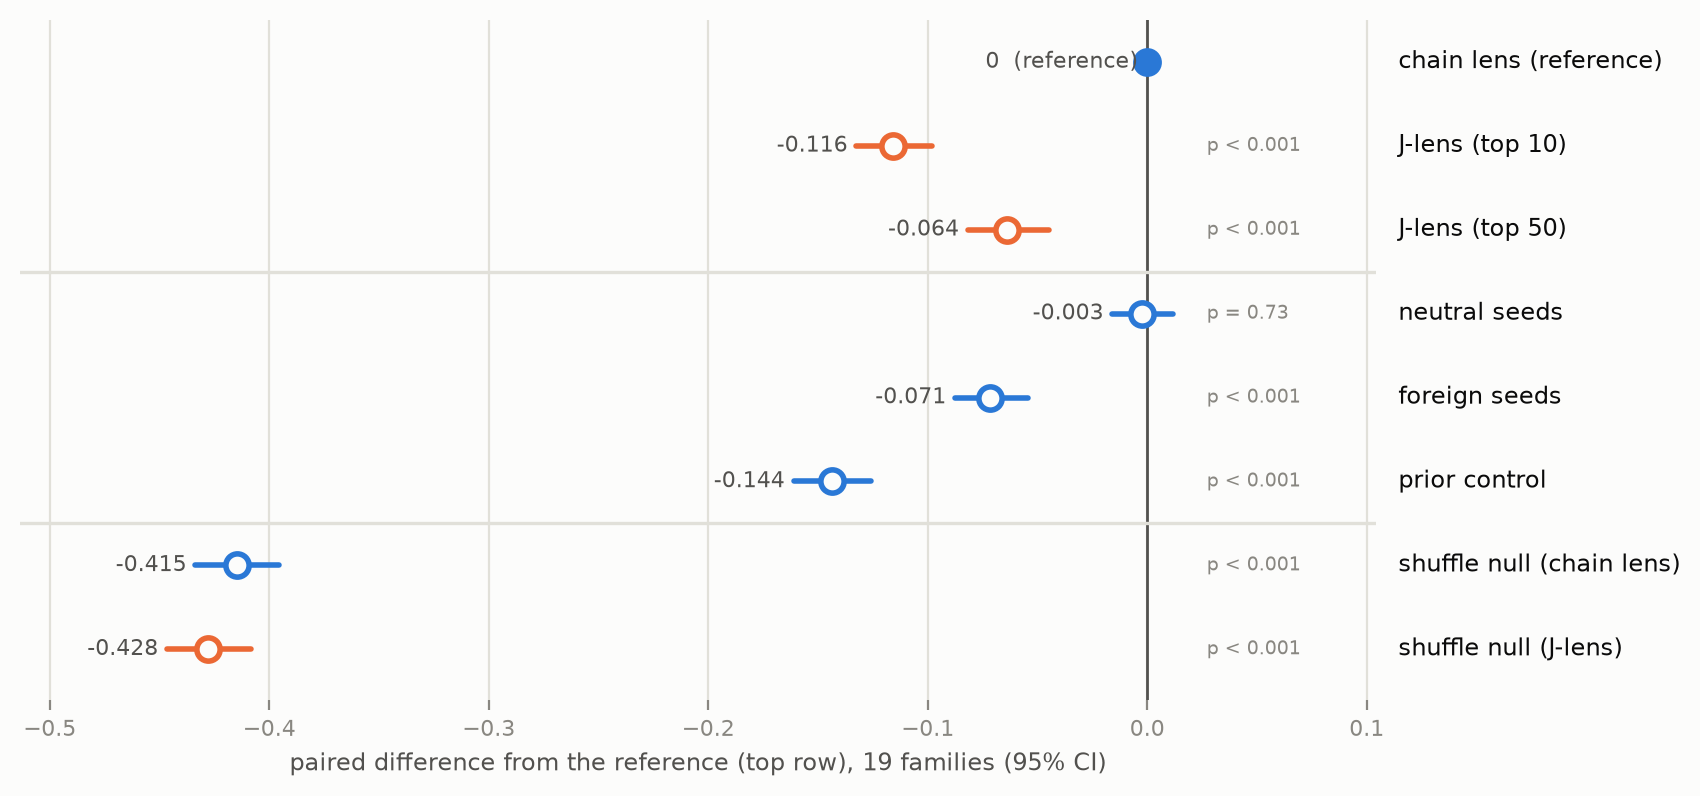
TLDR: This is an early draft of our new paper introducing a technique for recovering multi-token concepts from model activations. Our technique takes single-token methods like the J-lens and extends them by contrastively decoding on an MTP head. This gives improvements on WorkspaceBench, overall beating J-lens (0.42 vs 0.32 across all 28 families) and even a hindsight composite of the best untrained lens per task family (0.49 vs 0.41 across the 21 families with published scores). It especially improves on computational intermediate tasks, beating the trained oracle lens on arithmetic chain intermediates (0.42 vs 0.25).
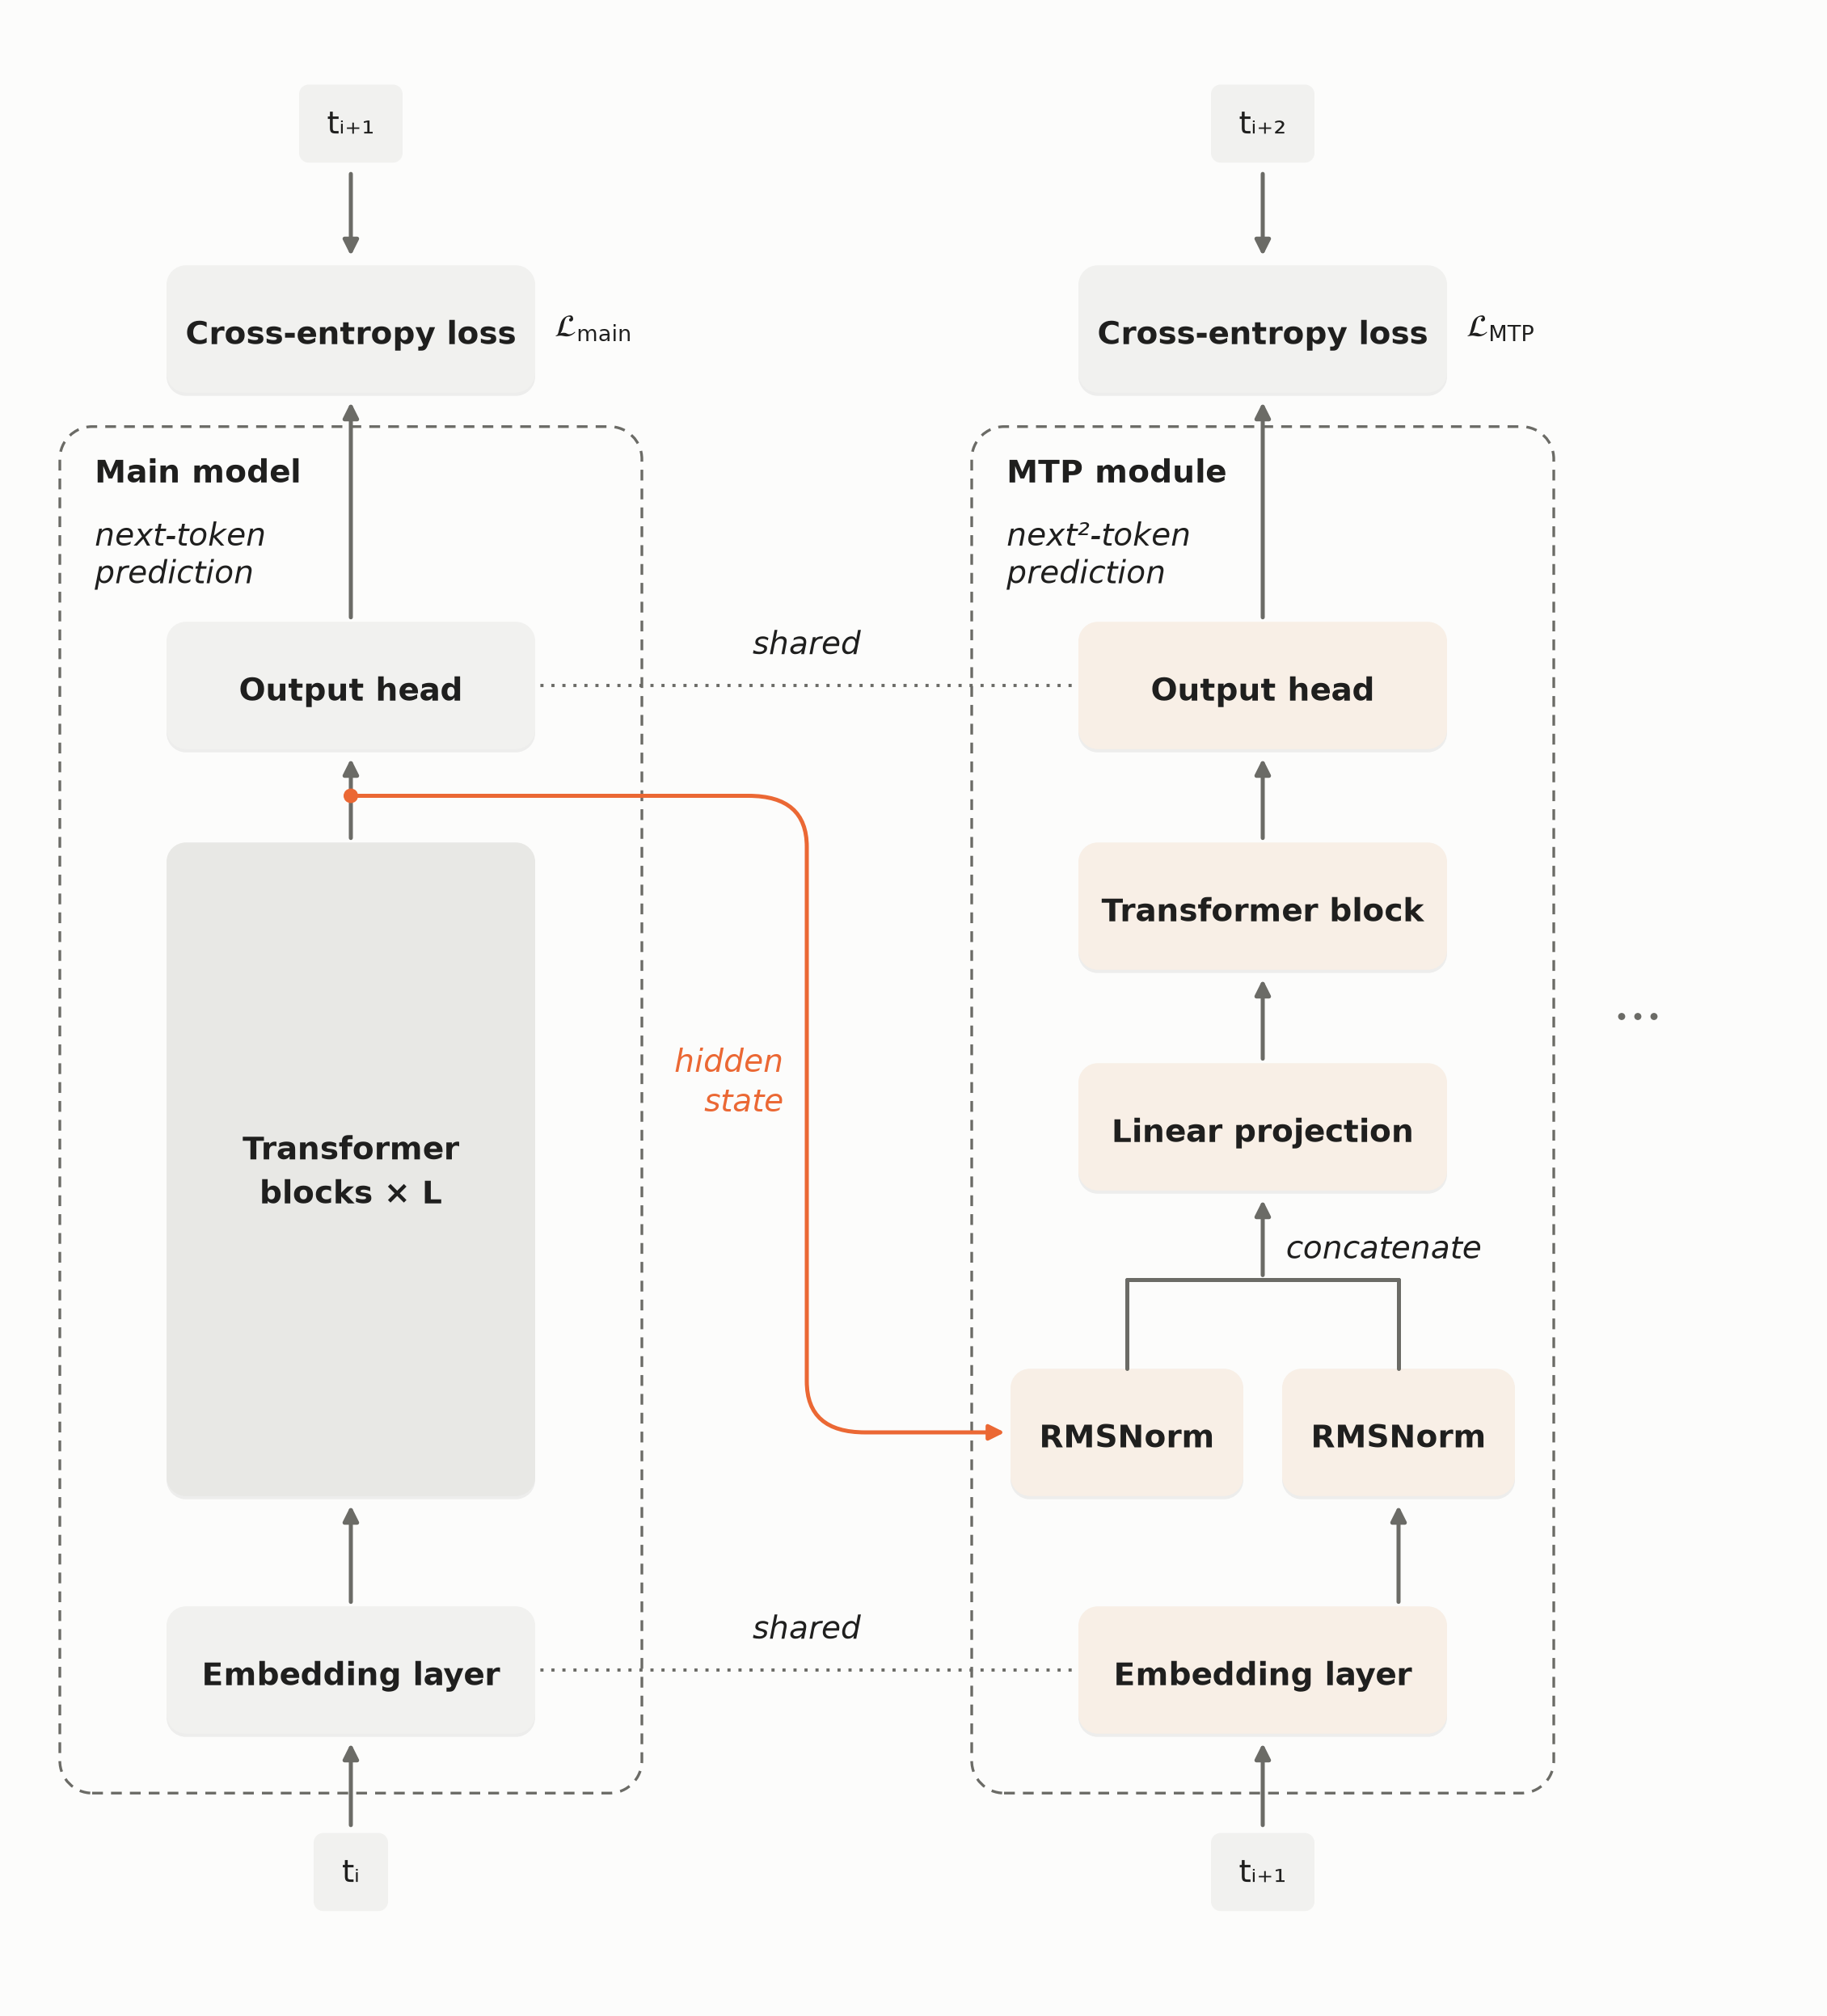
We introduce the chain lens, a new technique for extracting multi-token concepts from a model's latent representations. Our method takes single-token techniques like the logit lens or the J-lens and uses contrastive decoding on an MTP head to expand their readouts into bags of multi-token sequences. Generally speaking, it is good at surfacing specific multi-token concepts or pieces the model computes (such as arithmetic intermediates or phrases), although less good at rendering how those pieces relate: like the logit lens and J-lens, chain lens readouts are fragmentary.
On WorkspaceBench, a benchmark designed to identify good multi-token activation-to-text techniques, the chain lens beats a hindsight [...]
---
Outline:
(02:26) Background and related work
(05:33) Method
(07:35) Results and Discussion
(07:39) WorkspaceBench
(12:49) Workspace Sharing in Poetry Continuations
(15:44) Neuron Lens
(18:28) The Loom Lens
(19:35) Ablations
(21:56) Conclusion
---
First published:
November 11th, 2026
Source:
https://www.lesswrong.com/posts/Nr6fksEqqxNpdz6rk/the-chain-lens-interim
---
Narrated by TYPE III AUDIO.
---
Images from the article:
Apple Podcasts and Spotify do not show images in the episode description. Try Pocket Casts, or another podcast app.
Altri episodi di "LessWrong (30+ Karma)"
Non perdere nemmeno un episodio di “LessWrong (30+ Karma)”. Iscriviti all'app gratuita GetPodcast.